
Nvidia used the opening day of the Conference on Robot Learning in Austin to unveil GR00T 2, a new “world action model” that it says lets robots pick up delicate hand skills from videos of people, then master a new task from five demonstrations. The headline number is 95% success. The footnote, in Nvidia’s own whitepaper, is that the 50 test tasks were chosen from ones the model was already known to learn well.
Key points
- Nvidia introduced GR00T 2 on Nov. 9 at CoRL in Austin, describing it as an open world action model that predicts future video and robot actions together.
- Nvidia says it succeeds in 40% of trials on 50 tasks the target robot never practiced, 71% after one demonstration and 95% after five, but its whitepaper says those tasks were picked from ones the model learns to at least 80%.
- The model was pretrained on 402,730 hours of first-person video from about 51,500 people, plus handheld-gripper and robot data; 100,000 hours of the human video are public under CC BY 4.0.
- Foxconn, Siemens and Nexuni are testing GR00T 2, none has announced production use, and Nvidia lists the code as coming in December.
That doesn’t make GR00T 2 a dud. Parts of the research look like real progress, especially on two-handed, five-fingered work that earlier generalist models basically couldn’t do. But this is a company evaluating its own model on its own robots, and the way the numbers are framed matters. Here’s what Nvidia actually showed, how to read it, and what’s still missing.
What Nvidia announced in Austin
GR00T 2 is the successor to Nvidia’s Isaac GR00T N1 line, which started with a March 2025 paper and most recently shipped as GR00T N1.7, a 3-billion-parameter vision-language-action model on Hugging Face. A vision-language-action model, or VLA, looks at camera images, reads an instruction, and outputs motor commands.
The new model is a different kind of animal. According to Nvidia’s research page, GR00T 2 is built on Cosmos-Predict2.5-2B, Nvidia’s video-generation world model, and uses a single 2-billion-parameter diffusion transformer to “denoise future video and robot actions together.” In plain English: before it moves, the model generates a short clip of what it expects the next moment to look like from each of the robot’s cameras, and the action it picks is tied to that imagined future.
The release came bundled with a pile of other tools, per Nvidia’s blog post: Isaac Lab 3.0, its open-source robot training framework, now able to simulate cables and cloth with the Newton physics engine; two new industrial benchmarks called DexBench and VABAR; and an agent framework from UC Berkeley called Graph-as-Policy. Nvidia’s Jim Fan was scheduled to give a keynote at 1:50 p.m. Central on Monday titled “From Dreaming to Doing.”
Why “predict the video first” is the interesting idea
The biggest bottleneck in robot learning is data. Text models trained on the internet; robot models need recordings of robots doing things, usually captured by a human teleoperating the machine, one slow episode at a time. Human video is vastly more plentiful, but it has a problem: it contains no robot actions. A video of a person folding a towel doesn’t say which motor should turn how far.
Nvidia’s bet is that predicting video sidesteps that. If part of the training goal is “guess what the scene looks like next,” then every human video becomes useful practice, action labels or not. The whitepaper backs this with one of its more convincing experiments. Nvidia pretrained four versions of the model with none, 1%, 10% and all of its human video, then tested each on 72 tasks. Real-robot task progress rose from 50% to 70% as the human share grew, and the company says the curve hadn’t leveled off at the largest scale it tried.
Our read: if that scaling result holds up outside Nvidia’s lab, it’s the most important number in the release, more than any success rate. It would mean robot skill can grow with cheap human footage instead of expensive teleoperation hours.
The training set: 51,500 people filming their hands
The data behind GR00T 2 is enormous by robotics standards. Nvidia says it pretrained on 402,730 hours of first-person video of people working, 10,184 hours of demonstrations recorded with a handheld gripper across 2,897 tasks, and 23,500 hours of robot teleoperation spanning gripper arms, dexterous hands and Unitree’s G1 humanoid.
The whitepaper says the human footage, which it calls Human-1M, covers about 13.75 million episodes from more than 51,500 unique collectors in roughly 123,000 scenes, filmed in homes, workplaces, farms, commercial kitchens, shops and warehouses, plus about 80,000 hours from controlled studios. Nvidia has put 100,000 hours of it on Hugging Face as Human-1M-100K, listed under a CC BY 4.0 license. The other three-quarters stays in-house.
What the paper doesn’t describe is how those 51,500 people were recruited or paid. The Next Web notes that startups now pay people to film their chores for exactly this kind of training. That’s a labor story hiding inside a model launch: the “skills” GR00T 2 learns from human video are, quite literally, recorded from human workers.
How to read Nvidia’s numbers
The same experiment gets described three different ways depending on where you read about it. Here’s each figure and what it actually measures, with all results company-reported from Nvidia’s own evaluations:
- “40 of 50 tasks” zero-shot (the blog): the model succeeded at least once on 40 of 50 tasks with no demonstrations on the target robot. That’s coverage, not reliability.
- 40% zero-shot (the research page): the average trial success on those same tasks. This is the more honest “out of the box” number, and the blog’s feature list leaves it out.
- 71% with one demo, 95% with five: success after a 30-minute LoRA fine-tune (a cheap way to adapt a model by training a small add-on) on a single RTX 5090, using under three minutes of robot data for five demos. The whitepaper says 37 of 50 tasks then succeeded in every trial.
- The caveat: “The 50 tasks were chosen among those the model learns with five episodes (at least 80% success), so the five-episode rate is high partly by construction,” the whitepaper says. In other words, a 95% average over tasks pre-screened for scoring 80% or more is expected, not astonishing.
Nvidia deserves credit for printing that caveat in its own paper. It deserves less credit for a launch post whose bullet points don’t mention it.
What looks genuinely new
Strip out the cherry-picked headline, and several results are still striking, all company-reported:
- Two-handed dexterity. On seven tasks using Sharpa hands with 22 degrees of freedom each, such as filtering crude salt and swapping a GB300 memory module, Nvidia reports 68.6% average success for GR00T 2 versus at most 0.7% for its own GR00T 1.7 and Physical Intelligence’s pi-0.5.
- Learning without a robot demo. Shown chemistry-lab tasks only by people wearing gloves and cameras, a robot lined a funnel with filter paper and wet it in 65% of 20 trials, Nvidia says. A robot arm assembled a toy dump truck in 60% of trials after seeing it only done with a handheld gripper.
- Agents as supervisors. With a reasoning model calling GR00T 2 as a tool, watching progress and fixing dropped parts, a robot arm assembled three toys in 98, 97 and 97 of 100 trials from cluttered starts, versus 71 to 84 for the same policy without the agent.
- On-robot speed. A smaller 2-billion-parameter variant, GR00T 2 Turbo, makes a prediction in 124 milliseconds on the G1’s onboard Jetson Thor computer, and served popcorn in all 48 trials, per the research page.
Compare that with Apple’s simulation-trained G1 paper we covered Saturday, which reported 91% over 360 single-task trials. Both teams are converging on the same recipe: train on data that isn’t robot teleoperation (synthetic homes for Apple, human video for Nvidia), then lean on small amounts of real robot practice. Both also ran on the same Chinese-made Unitree G1, which says something about where research hardware is coming from.
Who’s actually using it
Nvidia says Foxconn is applying GR00T 2 to factory automation for server manufacturing, Siemens is evaluating it across industrial use cases, and Nexuni is testing it for robotic laundry handling. A startup called MicroAGI is using an RL-tuned version to swap Ethernet cables. As The Next Web points out, none of them has said it will use the model in production yet.
The Foxconn detail is the tell. Nvidia’s robots in the paper practice seating GB300 memory modules, the parts inside Nvidia’s own AI servers, and Foxconn builds those servers. Nvidia sells the chips, the simulation software, the onboard Jetson computers and now the robot brain that assembles the servers the chips go into. It’s a tidy loop, and it’s arriving the same week Nvidia’s board opened an investigation into its CEO, which is probably why GR00T 2 didn’t get much Monday airtime.
What’s missing
- The model itself. Nvidia calls GR00T 2 “open,” but the research page lists code as “Available in December,” and we found no GR00T 2 checkpoint on Nvidia’s Hugging Face page as of Monday morning Pacific. Until weights ship, “open” is a promise.
- Outside testing. Every success rate comes from Nvidia’s robots, tasks and evaluation setup. Nvidia did build a blinded head-to-head evaluation system, but its own limitations section says the Elo-style ratings have wide intervals and only 16 to 38 independent tasks per suite.
- Memory and touch. The model sees only 0.8 seconds of history, and the paper says tasks that need memory are handed to the agent. Force is something it predicts, not something it feels from sensors.
- The cost of going small. Turbo, the version that fits on a robot, drops from 68.6% to 34.3% on the dexterous tasks after post-training, according to the paper. The impressive hand work currently needs a workstation GPU nearby.
What to watch
- December’s release. Whether Nvidia ships GR00T 2 weights under the same NVIDIA Open Model License as N1.7, which allows commercial use, or something more restrictive.
- Independent replication of the human-video curve. The 50%-to-70% scaling result is the claim that matters; watch for labs using Human-1M-100K to test it on their own robots.
- A Foxconn production number. The first credible “this many units, this failure rate” figure from a server line would say more than any benchmark.
- The data supply chain. Who the 51,500 collectors are, how they consented, and what they were paid will matter more as human video becomes the main robot training input.
GR00T 2 is a serious research release with a real idea at its center: robots can learn physics by imagining the next frame, and that lets human video do the teaching. The 95% is the least interesting part, and the most carefully staged. Wait for the weights and for someone outside Santa Clara to run it.
Hype in. Signal out.
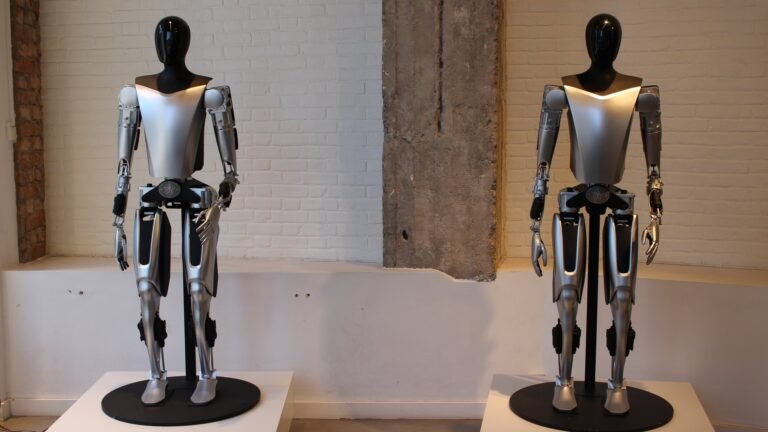
Image: A Unitree G1 humanoid at UAV Expo, November 2024. Nvidia says its smaller GR00T 2 Turbo model runs onboard a G1. Photo by Sayanesy via Wikimedia Commons, CC0 1.0 (public domain dedication). Resized for this post.